This week: neural net fundamentals
Classification Setup and Notation
training data:

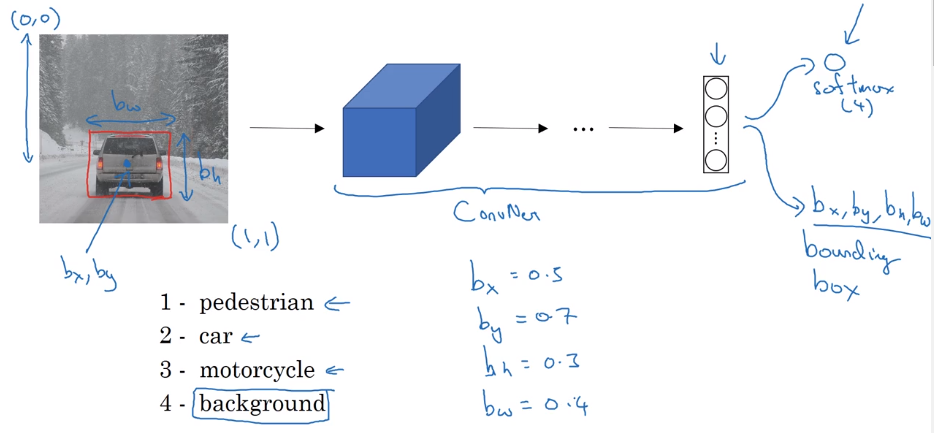
softmax classifier
(linear classifier — hyperplane):
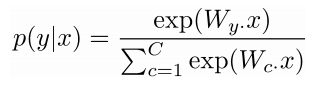
ith row of the param W: weight vector for class i to compute logits:
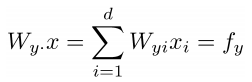
prediction = softmax of f_y:
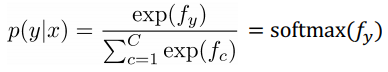
cross-entropy
goal: for (x, y), maximize p(y|x) ⇒ loss for (x, y) = -log p(y …
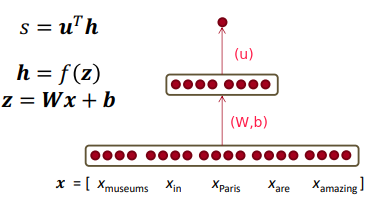
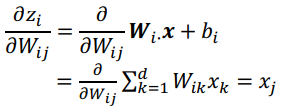
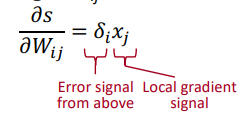 ⇒